Hi! I am Manan, a Research Scientist at Emergence AI, where I work on Reinforcement Learning with Verifiable Rewards (RLVR) for agentic AI systems, building agents that can reason, act, and improve through verifiable feedback. My research sits at the intersection of machine learning, optimization, and control theory, with a focus on developing principled, safe, and performant learning algorithms, spanning offline reinforcement learning, safety-constrained optimization, and generative policy learning. I am broadly interested in methods that combine data-driven learning with formal guarantees to build reliable intelligent systems.
I recently completed my PhD from the Indian Institute of Science (IISc) Bangalore, where I worked on safe learning and control under Prof. Shishir N. Y. Kolathaya and Prof. Pushpak Jagtap. Prior to that, I completed my B.Tech from Indian Institute of Technology Bombay (IITB) in 2021.
I also frequently collaborate with Prof. Somil Bansal’s SIA Lab at Stanford University and Prof. Rahul Mangharam’s xLab at University of Pennsylvania.
Before joining Emergence AI, I was a Visiting Researcher at Microsoft Research India, working on safe agentic reasoning for Vision-Language-Action (VLA) models under Dr. Akshay Nambi, and spent time at Fujitsu Research (NextGenAI Lab) improving VLA model inference under Dr. Manu Kaul. I have also worked as a Research Consultant at ARTPARK and as a Student Researcher at Washington University in St. Louis under Prof. Andrew Clark.
Click here for my detailed CV .
Follow me on Google Scholar, X (earlier twitter) and LinkedIn to keep informed with my latest research and projects.
News
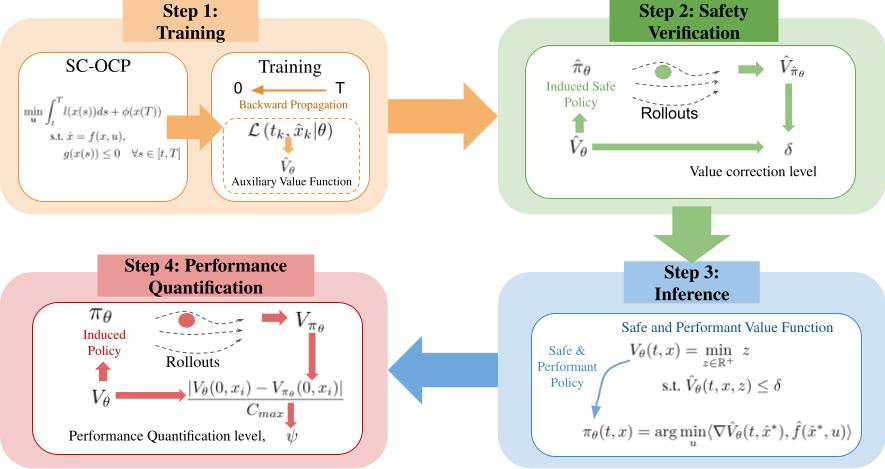
| Sep 24, 2026 | Our paper Bridging Safety and Performance in Autonomous Systems using Offline Reinforcement Learning has been accepted at NeurIPS 2026!  |
|---|---|
| Jul 13, 2026 | Excited to join Emergence AI as a Research Scientist, working on Reinforcement Learning with Verifiable Rewards (RLVR) for agentic AI systems!  |
| Jul 05, 2026 | Our work titled Safe Flow Q-Learning: Offline Safe Reinforcement Learning with Reachability-Based Flow Policies, has been accepted at the Reinforcement Learning Conference (RLC), 2026! |
| Jul 01, 2026 | Gave an invited talk at Microsoft Research India, Bangalore, on “Towards Safe Foundation Models for Robotic Systems”!  |
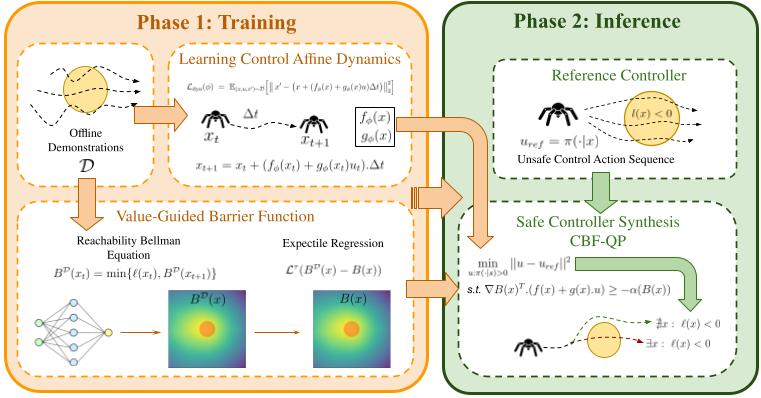
| Mar 28, 2026 | Our paper V-OCBF: Learning Safety Filters from Offline Data via Value-Guided Offline Control Barrier Functions has been accepted to Transactions on Machine Learning Research (TMLR)! Check out the project page. |